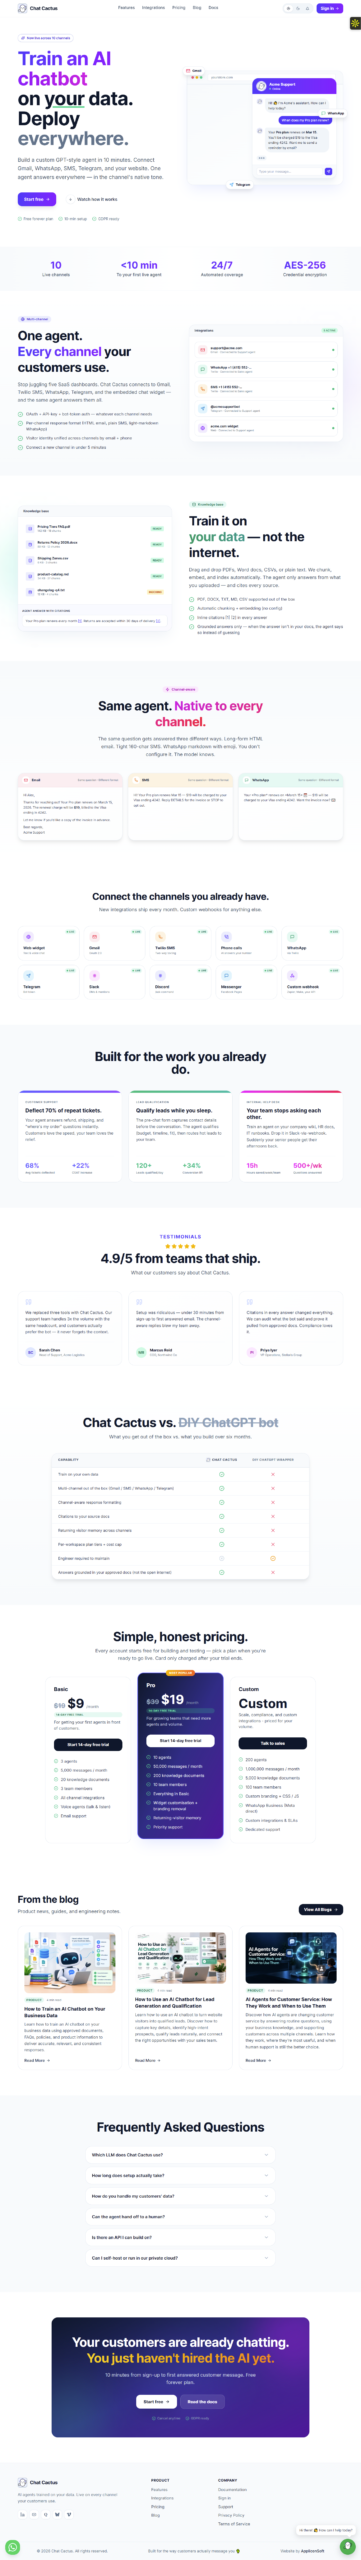
Chat Cactus
Chat Cactus is an AI-powered customer support platform that enables businesses to train intelligent agents on their own documents and deploy them across websites, Gmail, WhatsApp, SMS, and Telegram. It delivers accurate, source-cited responses using uploaded knowledge bases, helping businesses automate customer inquiries, qualify leads, and provide instant internal support. With easy document uploads, seamless channel integrations, scalable plans, and enterprise security features, Chat Cactus helps organizations streamline communication, reduce repetitive workloads, and deliver reliable support around the clock.
- Category: AI Automation Agency for Custom Business Solutions
- Client: Chat Cactus
- Date: 15/05/2024
- Website: https://chatcactus.com/
Client Challenge
ChatCactus needed an intelligent, 24/7 AI-powered customer… ChatCactus...
ChatCactus needed an intelligent, 24/7 AI-powered customer… ChatCactus needed an intelligent, 24/7 AI-powered customer support platform that could streamline inbound inquiries for businesses, support teams, and digital services. Companies were struggling with slow response times, rising operational support costs, and repetitive queries that overloaded human agents and delayed critical escalations. The platform required a seamless way to connect private knowledge bases, deliver fast and accurate answers with source citations, support real-time human agent handoffs, and offer an embeddable website widget that delivers consistent, reliable assistance around the clock.
The Solution
We developed and deployed an end-to-end AI customer…...
We developed and deployed an end-to-end AI customer… We developed and deployed an end-to-end AI customer support solution that combines real-time chat widgets, knowledge-assisted language models, automated inquiry routing, and human-in-the-loop agent workflows into one unified platform. ChatCactus ingests business documentation, FAQs, and product resources to deliver instant, context-aware answers while preventing hallucinations through grounded retrieval. When complex issues occur, the system smoothly escalates conversations to human support agents with full conversation history intact. The solution significantly reduces ticket backlogs, lowers first-response times to seconds, and provides a customizable, lightweight embed that integrates easily into any web application.
2. How the AI Workflow Works
What happens when a visitor sends a message to a ChatCactus agent (website widget; other channels follow the same path).
1. Request Checks.
The message is validated, the agent must be published, the website must be on the agent’s allowed-domains list, and per-visitor rate limits and the plan’s monthly message quota are enforced.
2. Visitor Context.
The visitor record is updated (page, referrer, language). If they have already filled in the lead form, their name and contact details are provided to the agent so it can address them personally.
3. Human-Handoff Check.
If a human has already taken over, the message goes to the team and the AI stays silent. An explicit “I want a human” request, or a keyword configured by the business, triggers immediate escalation.
4. Knowledge Retrieval.
The question is embedded and compared with the agent’s document chunks using cosine similarity. The four best matches above a relevance threshold are selected.
5. Prompt Assembly.
The agent’s persona, channel-specific style rules, escalation and lead-form rules, visitor details, retrieved sources (numbered for citation), and the last 10 messages are combined.
6. Model Call with Routing.
The request goes to the agent’s chosen model (OpenAI or Anthropic). A router falls back to a lighter model if a provider fails (circuit breaker) or if the workspace approaches its monthly AI cost ceiling.
7. Streaming Answer.
The reply streams to the visitor word by word. Only the sources actually cited by the model are displayed as citation chips.
8. Follow-Up Actions.
If the model indicates that a human is needed, the conversation is escalated and the team is notified. If the knowledge base cannot answer the question, the visitor is offered the lead form so the business can follow up.
9. Record Keeping.
Both messages, token counts, cost, model, and response time are stored for the transcript view, analytics, and billing.
3. Technical implementation
| Area | What is Used |
|---|---|
| AI Models | OpenAI GPT-4o and GPT-4o mini; Anthropic Claude Sonnet and Claude Haiku. The model is chosen per agent; super admins manage the available model list. |
| Retrieval (RAG) | OpenAI text-embedding-3-small embeddings; documents split into approximately 800-character overlapping chunks; cosine-similarity search; top 4 sources with inline citations. |
| Knowledge Ingestion | PDF, DOCX, CSV, Markdown, and plain-text uploads, plus pasted text. Text extraction with pdf-parse and mammoth. Files stored on local disk or Backblaze B2. |
| Voice | OpenAI Whisper (speech-to-text) and OpenAI TTS for the voice widget; Twilio Voice for phone calls. |
| Model Routing | Fallback chains between models, a per-provider circuit breaker, and a per-workspace monthly cost ceiling. |
| Web Application | Next.js 15 (App Router), React 19, TypeScript, Tailwind CSS 4, and NextAuth v5 (JWT sessions). |
| AI Service | Python FastAPI service (internal only): model calls, routing, embeddings, retrieval, ingestion, speech, and conversation/usage storage. Signed service tokens between the two services. |
| Database | MySQL, accessed by Prisma (web app) and SQLAlchemy (AI service). |
| Channels and Integrations | Website chat widget (text and voice), Twilio SMS, Voice and WhatsApp, Telegram, Slack, Discord, Facebook Messenger, Gmail, and signed webhooks for Zapier, Make, and n8n. |
| Public API | REST API (/api/v1/chat with streaming) with API keys and an OpenAPI description. |
| Billing and Email | Stripe (checkout, customer portal, invoices, and webhooks); Resend with SMTP fallback for email. |
| Operations | nginx, PM2, and Let’s Encrypt on a Linux server; structured JSON logs; Sentry error tracking; request IDs traced across both services. |
4. Architecture Diagram
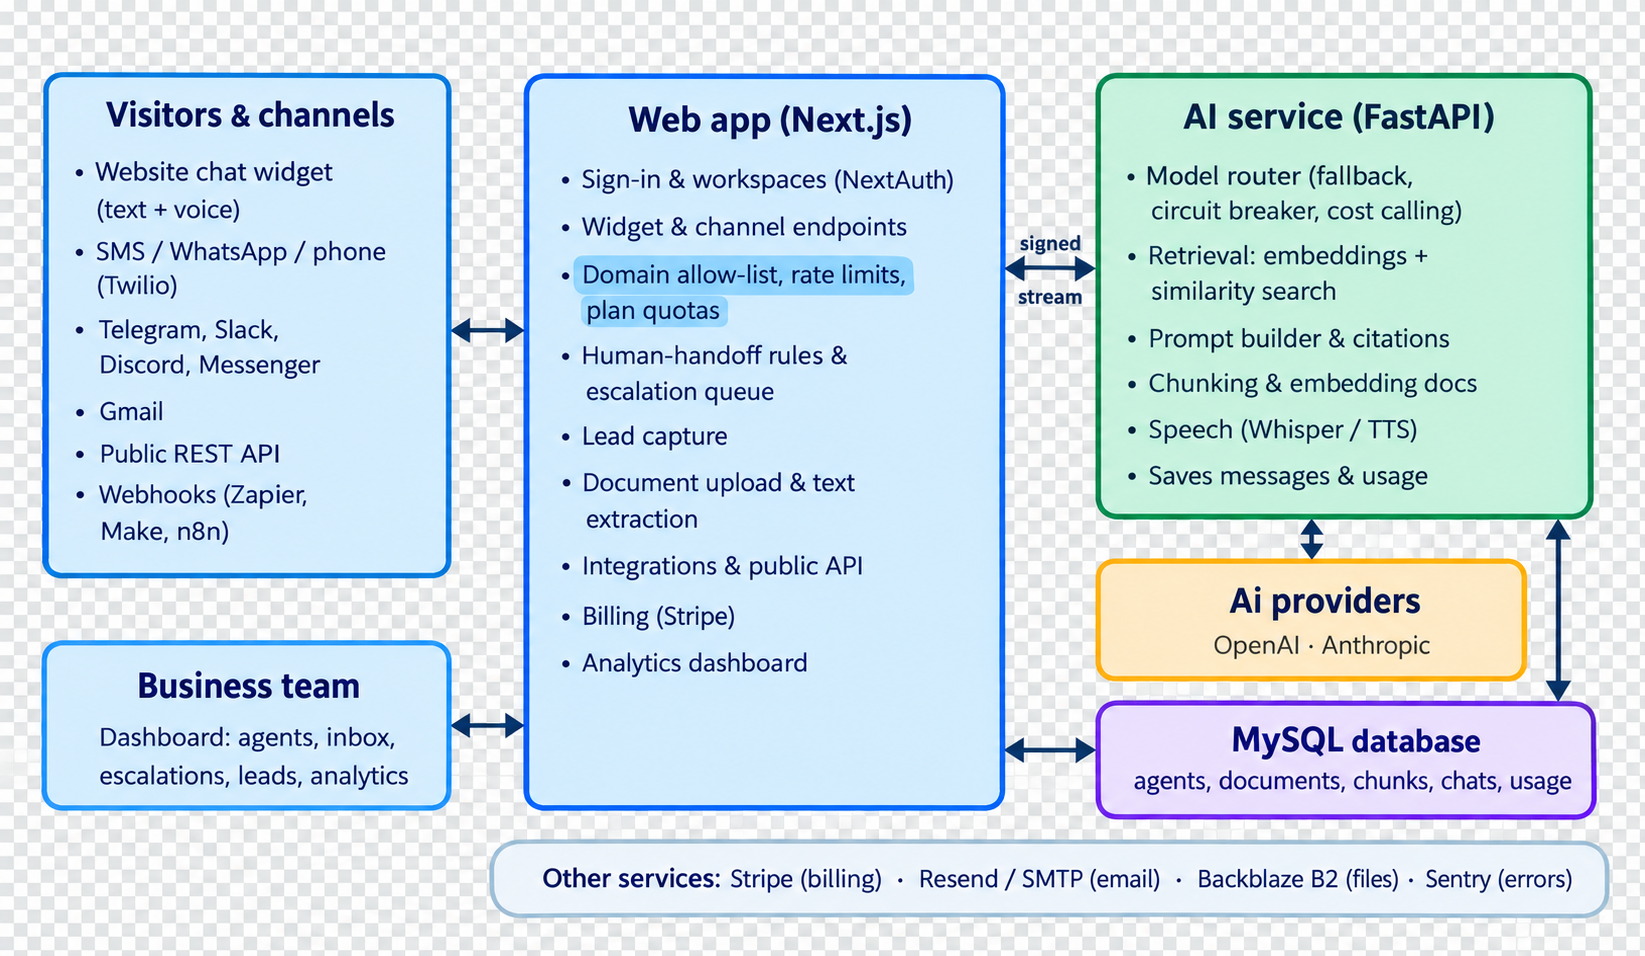
The web app is the only public entry point. It applies security, quota and handoff rules, then calls the internal AI service over a signed connection. The AI service retrieves knowledge, calls the model and streams the answer back. Both services share one database.
5. Deployment evidence
| Item | Details |
|---|---|
| Live Product | https://chatcactus.com — Public sign-up, pricing, blog, and documentation. |
| Live AI Features | Website chat widget (text and voice), knowledge-base answers with citations, human escalation inbox, lead capture, multi-channel integrations, public chat API, and analytics. |
| Working Demo | The ChatCactus website runs its own ChatCactus agent in the chat widget, so a working demo is available on the live site. Customers can embed the same widget on their websites using a one-line script. |
| Hosting | Linux server with nginx (HTTPS via Let’s Encrypt) and PM2 running the Next.js web app and the FastAPI AI service, with a MySQL database. |
| Release Process | GitHub pull requests are merged into the main branch, then deployed using git pull, build, and restart. An in-app “What’s New” changelog informs users about updates. |
| Current Status | To confirm before publishing: live/available, with the date checked. |
6. Performance metrics
No measured production figures yet. We did not invent any numbers. The product already records the data below, so real figures can be taken from production for a stated date range. The landing page’s “68% tickets deflected”, “+22% CSAT” and “120+ leads/day” are marketing examples with no measurement behind them, and should not be reused as evidence.
| Metric | Source in the Product | Value |
|---|---|---|
| AI Response Time (Mean / Median) | Response time recorded for every AI reply (usage logs; shown as “Mean LLM Latency” in Analytics). | To measure |
| Conversations and Messages Handled | Conversation and message records; Analytics dashboard. | To measure |
| Handled Without a Human (Containment) | Share of conversations never escalated: 100% minus the escalation rate shown in Analytics. | To measure |
| Human Handoff Speed | Average minutes to assignment, first human reply, and resolution (escalation timestamps). | To measure |
| Leads Captured | Lead records per agent and per period. | To measure |
| Answers Grounded in Knowledge | Share of AI replies that cited a source (citations returned with each reply). | To measure |
| Cost per Conversation | Token cost recorded per reply (usage logs). | To measure |
| Uptime | Not tracked in the product; requires an external uptime monitor. | Not available |
| Answer Accuracy / CSAT | Not tracked in the product (no rating system); requires a reviewed sample of conversations. | Not available |
Recommended method: take a fixed 30-day window from production, state the dates and the number of conversations, and publish median as well as mean response time.
7. Case study details
Business problem
Small and mid-sized businesses get the same customer questions all day on their website and messaging apps: opening hours, pricing, orders, bookings. Answering them takes staff time; after hours, questions go unanswered and potential customers leave without sharing their contact details.
Implemented solution
A no-code platform where a business uploads its own documents and launches an AI agent in minutes. The agent answers from those documents with citations, works across the website and messaging channels, collects leads when it can’t answer, and hands the conversation to a human with full context when needed.
What AppliconSoft built
- The full product: multi-tenant web app, internal AI service, admin console and billing.
- Retrieval with citations and a model router that switches models when a provider fails or a workspace nears its cost ceiling.
- Human escalation with queue, assignment and response-time tracking.
- Eight messaging integrations, a public API, voice chat and Stripe subscriptions.
- In-app Help Center with guided tours, and an in-app changelog.
Human review and failure handling
- Visitors can ask for a human at any time; the business can also set keywords that always escalate.
- When a human takes over, the AI stops replying in that conversation.
- If the knowledge base has no answer, the agent says so and offers the lead form instead of guessing.
- Provider outages fall back to another model automatically; per-plan quotas and cost ceilings prevent runaway spend.
Measurable outcomes
Pending. Fill in from the production measurements in section 6 (for example: conversations handled per month, share resolved without a human, median response time, leads captured). Add a customer quote only with that customer’s written approval.
"ChatCactus brings our customer support operations together in one place, making it effortless to deliver instant, accurate answers and handle inquiries around the clock. The automated knowledge retrieval and smooth agent handoff have made resolving customer tickets much faster and significantly reduced our team's workload."